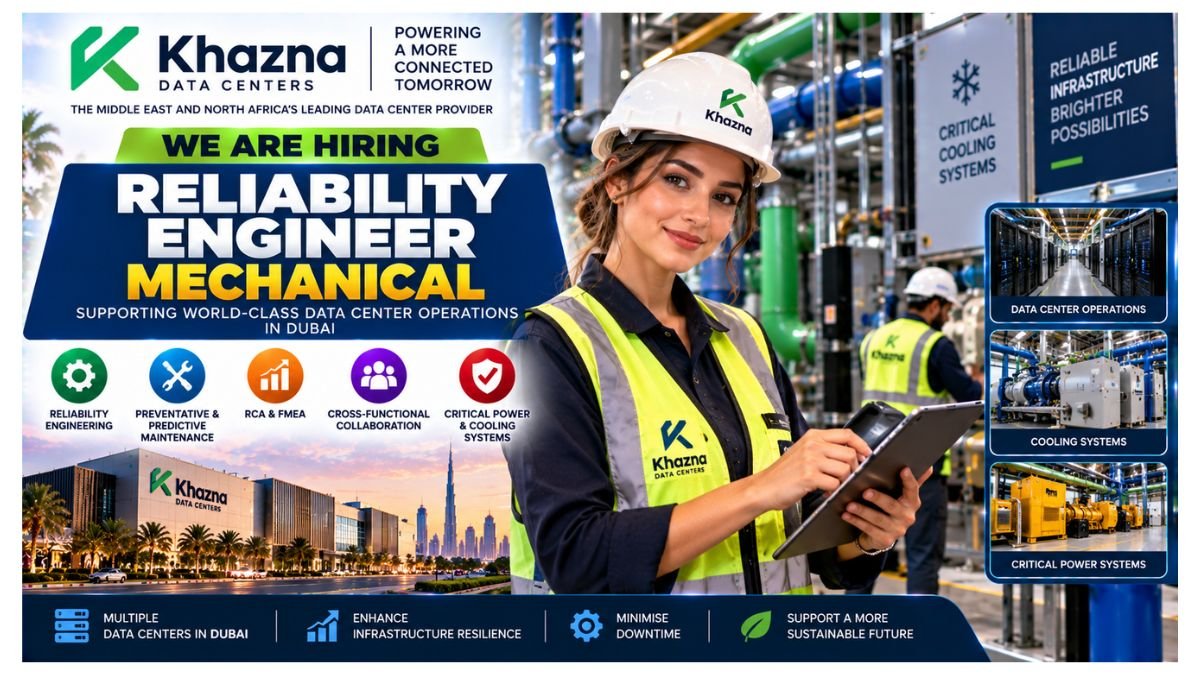
Khazna Data Centers — founded in 2012 and now the leading and trusted wholesale data center provider in the Middle East and North Africa region — is seeking a Site Reliability Engineer (Mechanical) to support the reliability engineering programme across multiple data centers in Dubai. Reporting to the Reliability Manager, you will monitor system performance, drive preventative and predictive maintenance initiatives, lead Root Cause Analysis (RCA) and FMEA, and collaborate with cross-functional teams to minimise downtime and enhance infrastructure resilience across critical power, cooling, and IT systems.
About Khazna Data Centers — MENA’s Wholesale DC Leader
Company: Khazna — founded 2012, the leading and most trusted wholesale data center provider across MENA — delivering industry benchmark power supply and cooling services across the UAE and wider region
Reliability Scope: Critical power, cooling, and IT systems across multiple data center sites — real-time and historical performance monitoring, RCA, FMEA, predictive and condition-based maintenance
Technology Tools: IoT sensors, machine-learning frameworks, condition-based monitoring systems, data analytics platforms, Python/R scripting, and monitoring platforms
KPI Framework: MTBF, MTTR, and availability — standardised data collection, reliability reporting, and dashboard presentation to site leadership
Standards: Uptime Institute, ISO, ASHRAE — full compliance across data center reliability engineering activities
Khazna & Dubai Data Center Market — Why This Role
Strategic Context: Dubai — the MENA region’s fastest-growing data center market — is experiencing unprecedented demand for wholesale colocation driven by cloud adoption, AI infrastructure, and digital transformation across the Gulf — creating sustained demand for senior reliability engineers at Khazna’s expanding fleet
Market Leadership: Khazna’s position as MENA’s leading wholesale data center provider means this reliability engineering role sits within the most strategically significant critical infrastructure organisation in the region — where the consequences of downtime are measured in SLA exposure and client trust
Technology Frontier: Khazna’s adoption of IoT sensors, machine learning frameworks, and predictive maintenance analytics positions this role at the leading edge of what data center reliability engineering looks like today
Career Growth: Progression toward Senior Reliability Engineer, Reliability Manager, and Director of Infrastructure Resilience within Khazna’s growing MENA data center fleet
Position Overview
This Site Reliability Engineer — Mechanical role at Khazna in Dubai covers the full scope of data center reliability engineering — from monitoring real-time and historical performance metrics for critical power, cooling, and IT systems, through analysing system data to identify failure modes and reliability risks, executing RCA and FMEA and driving corrective and preventive actions, developing condition-based and predictive maintenance routines using IoT and machine learning, supporting preventive maintenance programmes, contributing to asset lifecycle and capacity planning, implementing availability management and risk mitigation plans, maintaining MTBF/MTTR/availability KPIs, preparing reliability reports and dashboards, leading failure-response during site incidents, and collaborating with Operations, Engineering, Facilities, and Vendors to embed reliability best practices across the fleet.
Why This Role Matters: As Site Reliability Engineer at Khazna in Dubai, you are engineering the resilience of the critical infrastructure that the MENA region’s most demanding enterprise, cloud, and hyperscale customers depend on — because in a wholesale data center, power outages, cooling failures, and unplanned downtime are not inconveniences but SLA breaches with financial, reputational, and contractual consequences that Khazna’s reliability programme exists to prevent, apply your RCA, FMEA, and predictive maintenance expertise in a data center environment where your ability to identify failure modes before they cause outages — using IoT sensor data, machine learning anomaly detection, and condition-based monitoring — is the direct, measurable value you deliver to the organisation every day, work at the frontier of data center reliability engineering — using Python or R for data analysis, integrating IoT sensor feeds, applying machine-learning frameworks to equipment health monitoring, and building the condition-based maintenance routines that progressively reduce Khazna’s reliance on reactive maintenance across its multi-site fleet, lead failure-response during site incidents — applying the structured, evidence-driven engineering discipline to ensure that not only is the immediate problem resolved but the root cause is identified, documented, and prevented from recurring through systematic corrective and preventive action, and build a reliability engineering career with MENA’s leading wholesale data center provider — in Dubai’s most technically demanding and fastest-growing critical infrastructure market, where MTBF improvement, MTTR reduction, and infrastructure resilience are mission-critical goals that your engineering work directly achieves.
Key Responsibilities
Performance Monitoring, Data Analysis & Reliability Risk
- Monitor real-time and historical performance metrics for critical power, cooling, and IT systems across Khazna’s data center fleet — maintaining continuous visibility of system health status
- Analyse system data to identify trends, failure modes, and reliability risks — applying data analytics, Python/R scripting, and monitoring platform outputs to proactive reliability management
- Ensure data collection and reporting processes for reliability KPIs — MTBF, MTTR, and availability — are standardised, accurate, and consistently maintained across all sites
- Prepare reliability reports and dashboards — presenting findings, trend analysis, and actionable recommendations to site leadership and the Reliability Manager
RCA, FMEA & Corrective / Preventive Action
- Execute Root Cause Analyses (RCA) following equipment failures and site incidents — driving corrective and preventive actions through to verified closure with documented evidence
- Conduct Failure Mode and Effects Analyses (FMEA) for critical data center equipment and systems — identifying potential failure modes before they cause service-impacting events
- Respond to and lead failure-response efforts during site incidents — ensuring rapid recovery and root-cause follow-through to prevent recurrence across the data center fleet
- Implement and enforce availability management plans, risk assessments, and mitigation strategies — maintaining Khazna’s infrastructure resilience against the most probable and highest-consequence failure scenarios
Predictive & Preventive Maintenance — IoT & Machine Learning
- Develop and maintain condition-based and predictive maintenance routines — leveraging IoT sensors, data analytics platforms, and machine learning tools to detect equipment degradation before failure
- Support preventive maintenance programmes — scheduling, documenting, and validating maintenance activities to ensure they are completed to standard and on time across the fleet
- Propose continuous-improvement initiatives and pilot emerging reliability technologies — staying at the leading edge of what data center reliability engineering can achieve with modern tools and methodologies
- Collaborate with Operations, Engineering, Facilities, and Vendors to integrate reliability best practices into day-to-day data center workflows and standard operating procedures
Asset Lifecycle, Capacity Planning & Standards Compliance
- Assist in asset lifecycle planning — including equipment upgrades, decommissioning strategies, and end-of-life replacement planning across critical power and cooling infrastructure
- Contribute to capacity runway assessments — forecasting infrastructure needs and supporting data-driven investment decisions for Khazna’s expanding data center fleet
- Maintain compliance with industry reliability standards and regulations — Uptime Institute, ISO, and ASHRAE — across all reliability engineering activities and documentation
- Maintain familiarity with IoT sensor systems, machine-learning frameworks, and condition-based monitoring platforms as they evolve within Khazna’s reliability engineering toolkit
Qualifications & Requirements
Educational Requirements
- Bachelor’s degree in Mechanical Engineering, Electrical Engineering, Reliability Engineering, or a related discipline
Experience Requirements
- 3+ years of experience in reliability engineering, maintenance engineering, or a data center operations environment
- Hands-on experience with RCA, FMEA, and predictive maintenance methodologies
- Proficiency with monitoring platforms, data-analytics tools, and scripting — Python or R preferred
- Familiarity with IoT sensors, machine-learning frameworks, and condition-based monitoring systems
- Knowledge of industry reliability standards — ISO, ASHRAE, and Uptime Institute
Personal Competencies
- Strong analytical and problem-solving skills with acute attention to detail in reliability data interpretation
- Effective communicator — able to present technical reliability findings to diverse audiences including site leadership and non-technical stakeholders
- Project coordination skills with the ability to manage multiple concurrent reliability initiatives across a multi-site data center fleet
- Collaborative mindset — comfortable working in cross-functional teams with Operations, Engineering, Facilities, and external Vendors
- Self-starter with a continuous-improvement attitude and genuine commitment to infrastructure resilience
About Khazna Data Centers — MENA’s Reliability Standard-Setter
Founded in 2012, Khazna has grown rapidly to become the leading and most trusted wholesale data center provider in the Middle East and North Africa. Through its data centers, Khazna provides industry benchmark levels of power supply and cooling services to serve the growing demand for data center operations across the UAE and the wider MENA region. As the region’s leading wholesale DC provider, Khazna’s commitment to infrastructure reliability, operational excellence, and engineering innovation is reflected in the quality of its reliability engineering programme — making this Site Reliability Engineer role a genuine opportunity to contribute to the technical foundation of MENA’s most critical digital infrastructure at a time of unprecedented regional growth in cloud, AI, and enterprise colocation demand.
Career Excellence: Join Khazna Data Centers as Site Reliability Engineer in Dubai — where RCA, FMEA, MTBF/MTTR analysis, IoT-driven predictive maintenance, Python data analytics, and Uptime Institute/ISO/ASHRAE standards compliance combine in MENA’s most prestigious and technically advanced data center reliability engineering role.
Who Should Apply?
- Reliability Engineers — Data Center: With 3+ years of reliability or maintenance engineering experience in data center, critical infrastructure, or industrial environments
- RCA / FMEA Specialists: With hands-on Root Cause Analysis, Failure Mode and Effects Analysis, and corrective/preventive action management experience
- Predictive Maintenance Engineers: With IoT-based condition monitoring, machine-learning-assisted fault detection, and data-analytics-driven maintenance planning experience
- Data Center Operations Engineers: With critical power, cooling, or IT systems monitoring and reliability KPI (MTBF/MTTR/availability) management experience
- Python/R Data Engineers — Reliability: With scripting capability for reliability data analysis, reporting automation, and monitoring platform integration in a critical infrastructure environment
Recently Opening Job👇