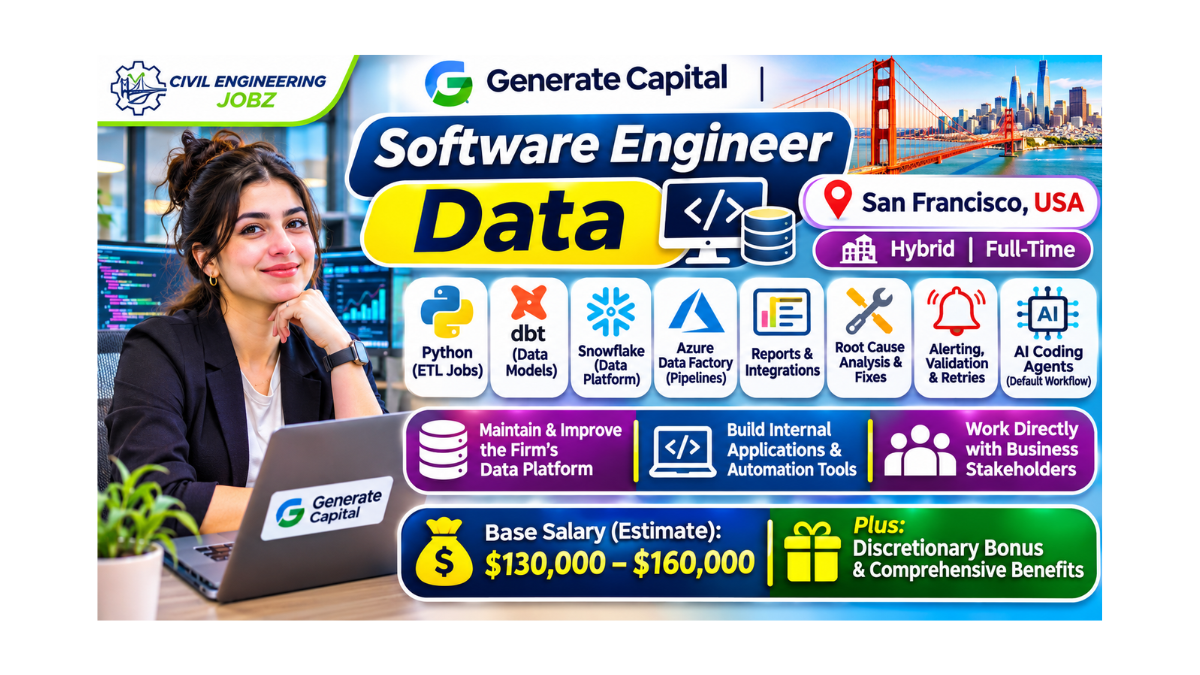
Generate Capital is hiring a Software Engineer, Data in San Francisco to keep the firm’s data platform healthy and help build the internal tools that will replace manual work and outside software. This is a hybrid, full-time role for an engineer who would rather fix the system than fix the same ticket twice. You’ll own the day-to-day health of Python ETL jobs, dbt models in Snowflake, Azure Data Factory pipelines, and the reports and integrations that depend on them. When something fails, you’ll trace it to its root cause, whether that’s a vendor schema change, an API rate limit, a failed model test, or a broken dependency, and then fix it. You’ll work directly with business stakeholders to understand the impact of each issue and confirm that the fix really solved their problem. Recurring issues become design work: you’ll add the alerting, validation, retries, and schema-change handling that stop a whole class of failure. You’ll also help build and run internal applications, sit with stakeholders to turn their problems into prototypes, and use AI coding agents as your default way of working. The reasonable base salary estimate is $130,000 to $160,000, plus a possible discretionary bonus and benefits.
About Generate Capital — Data & Technology in Financial Services
Company: Generate Capital
Team: Data & Technology, which runs the firm’s data platform
Direction: Replacing SaaS tools, spreadsheets, and manual processes with software built in-house
Industry: Financial services, with data-heavy operations
Location: San Francisco, California (hybrid)
Software Engineer, Data Role — Pipelines, Root Cause & Internal Tools
Department: Data & Technology
Primary Focus: Pipeline reliability, root-cause fixes, internal applications
Scope: Python ETL, dbt models, Snowflake, Azure Data Factory, and downstream reports
Mission: Building a data platform the whole firm can depend on
Software Engineer, Data Position Overview
The Software Engineer, Data role sits at the centre of the firm’s data work, with two jobs that feed each other. The first is keeping the current platform healthy. Python ETL jobs, dbt models running in Snowflake, Azure Data Factory pipelines, and the reports and system integrations built on top of them all need steady attention, and you’ll own that day-to-day health. Failures are inevitable, so the skill that matters most is triage. A broken load might come from a vendor who changed a schema without warning, an API that started rate-limiting requests, a model test that caught bad data, or a dependency that stopped working. You’ll work from the symptom back to the cause, often in code you didn’t write and under time pressure, and then make a fix that holds. The second job is building what comes next. The team is replacing outside SaaS tools, spreadsheets, and manual processes with software it builds itself, so you’ll help ship and run internal applications, translate stakeholder problems into requirements and working prototypes, and turn them into tools people use. Stakeholders are part of the work, not an interruption to it. You’ll keep people informed about what went wrong and what is being done, and you’ll confirm afterwards that the resolution met their needs. Engineering judgement also means looking ahead: you’ll find weaknesses in process, architecture, code quality, and security before they break, and you’ll help define repeatable patterns for testing, logging, deployment, and secrets handling. Working with the wider data team on fixes, code reviews, and releases keeps quality consistent, and AI coding agents are part of how you do this every day, with your workflows shared so the whole team moves faster.
As Software Engineer, Data, you’ll develop depth in data platform engineering, cloud operations, and the discipline of building tools that last. The role asks for two to three years of professional software or data engineering experience, though exceptional new graduates with substantial shipped work are considered. Strong Python and SQL are essential, along with experience building or operating software in a cloud environment. Azure is preferred, while AWS or GCP experience is welcome. Experience with Snowflake and dbt is a plus, as are internal tools or full-stack applications and a background in financial services, energy, or another data-heavy field. You’ll need to be comfortable debugging systems you didn’t build, translating business problems into technical solutions, and communicating clearly, both in conversation and in writing. Self-awareness, curiosity, integrity, and a practical, entrepreneurial attitude matter as much as technical skill, and a willingness to say that perfect can be the enemy of the good is valued. For data engineers in San Francisco who want their work to remove repetitive toil for a whole firm, this hybrid role offers a strong combination of reliability work and real building.
Why This Role Matters: As Software Engineer, Data at Generate Capital, you keep the pipelines the whole firm relies on running, turn recurring failures into permanent fixes, build internal tools that replace outside software and manual work, work directly with the people who use your code, adopt AI-assisted engineering as a daily practice, and advance a career in data platform engineering in San Francisco.
Key Responsibilities & Engineering Duties
Data Pipeline Operations
- Own the day-to-day health of Python ETL jobs
- Maintain dbt models running in Snowflake
- Support Azure Data Factory pipelines
- Keep downstream reports and system integrations working
- Monitor data loads and flag problems early
- Review model test results and act on failures
Root-Cause Triage & Fixes
- Trace failures to their root cause quickly
- Handle vendor schema changes and their knock-on effects
- Resolve API rate-limit and integration issues
- Fix failed model tests and broken dependencies
- Work through problems in code you did not write
- Confirm that each fix holds under real conditions
Stakeholder Communication
- Understand the business impact of each issue
- Keep affected stakeholders informed during incidents
- Confirm that resolutions solved the real problem
- Turn stakeholder problems into clear requirements
- Sit with business teams to shape prototypes
- Explain technical trade-offs in plain language
Reliability & Recurring-Issue Design
- Treat recurring tickets as design problems
- Add alerting, validation, and retries where they are missing
- Handle schema changes in a controlled way
- Prevent whole classes of failure from returning
- Proactively find weaknesses before they cause outages
- Drive fixes for process, architecture, and code quality gaps
Internal Applications & Tools
- Help build internal applications that replace SaaS tools
- Replace spreadsheets and manual processes with software
- Ship and run internal applications after launch
- Build prototypes that stakeholders can test quickly
- Keep internal tools maintainable and well documented
- Support adoption of new tools across the business
Quality, Security & Team Practice
- Help define repeatable standards for testing and logging
- Apply consistent patterns for deployment and secrets handling
- Take part in code reviews and releases with the data team
- Share AI-assisted workflows so the team gets faster
- Use AI coding agents as a default way of working
- Document systems, decisions, and operational runbooks
Qualifications & Requirements
Experience
- 2 to 3 years of professional software or data engineering experience
- Exceptional new graduates with substantial shipped work are considered
- Experience debugging systems under time pressure with incomplete information
Technical Skills
- Strong Python
- Strong SQL
- Experience building or operating software in a cloud environment
- Azure experience (preferred), or AWS or GCP experience
- Comfort using AI coding agents as part of daily development
Advantageous Experience
- Snowflake and dbt
- Building internal tools or full-stack applications
- Financial services, energy, or other data-heavy environments
Professional Qualities
- Ability to translate business problems into technical solutions
- Outstanding communication, empathy, and listening
- Strong writing and documentation skills
- High self-awareness and humility
- Intellectual agility, curiosity, and creativity
- Entrepreneurial spirit and comfort with risk
- Unimpeachable integrity
Career Development & Growth Opportunities
Professional Advancement
- Pathway toward Senior Data Engineer or Platform Engineering lead roles
- Opportunity to shape data platform architecture and standards
- Growth into product-minded internal tooling leadership
- Influence on how a whole firm builds and runs its software
Learning & Development
- Hands-on work across ETL, dbt, Snowflake, and Azure
- Experience building production internal applications
- Practice with AI-assisted engineering workflows
- Close work with business stakeholders and their problems
Compensation & Benefits
- Estimated base salary range of $130,000 to $160,000
- Possible discretionary bonus
- Health care and retirement benefits
- Paid time off, sick leave, and parental leave
About Generate Capital — Building the Firm’s Own Software
Generate Capital’s Data & Technology team runs the data platform that the whole firm depends on. The team is steadily replacing SaaS tools, spreadsheets, and manual processes with software it builds itself, and it values engineers who take ownership, learn from failures, and bring the people who use their work into the process. The company is an equal opportunity employer.
Career Excellence in Data Engineering: Join a financial services firm in San Francisco, keep mission-critical data pipelines healthy, build internal tools that replace outside software, work closely with stakeholders, and grow a career in data platform engineering.
Who Should Apply?
- Data Engineers: Ready to own pipeline reliability
- Python Developers: Wanting to work on data platforms
- Analytics Engineers: Familiar with dbt and Snowflake
- Backend Engineers: Interested in internal tools
- Recent Graduates with Shipped Work: Ready for a serious data role
- Fintech and Energy Data Specialists: Seeking a data-heavy environment
Recently Opening Job👇