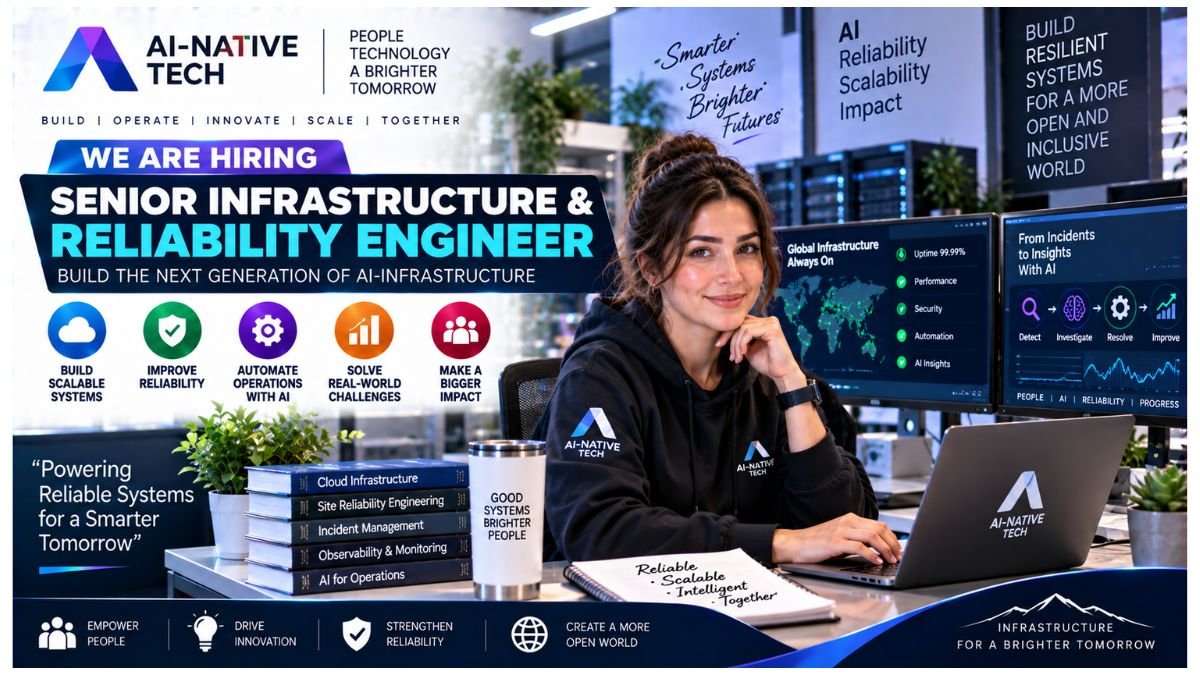
We’re building an AI-native Infrastructure & Reliability organization where autonomous agents investigate incidents, validate hypotheses, generate RCAs, and safely remediate production issues, and are hiring a Senior Infrastructure & Reliability Engineer to help build and operate this platform.
About the Role — AI-Native Reliability Engineering
Core Scope: Owning production reliability while improving AI agents that automate incident response
Platform Focus: Enterprise-scale SaaS with strong AWS production experience
AI Tooling: Using tools such as Claude Code, Codex, Cursor, or Warp
Work Format: Fully remote, global team
Culture: AI-first, with no limits on AI tooling or compute
Career Impact & AI-Native SRE Opportunity
Total Flexibility: Fully remote role, part of a global team
Technical Ownership: Own production reliability and resolve customer-impacting incidents
Innovation Focus: Build AI agents for incident triage, change validation, and auto-remediation
Career Growth: Help build one of the industry’s first AI-native Infrastructure & Reliability organizations
Position Overview
You’ll own production reliability while continuously improving the AI agents that automate incident response, operational workflows, and infrastructure management. Engineers here are measured not by the number of tickets they close, but by the AI systems they build to eliminate them.
Why This Role Matters: As Senior Infrastructure & Reliability Engineer, you own production reliability, responding to and resolving customer-impacting incidents, build and improve AI agents for incident triage, change validation, RCA generation, and auto-remediation, execute production deployments and infrastructure changes with strong operational discipline, write production code, automation, runbooks, and AI workflows that eliminate repetitive operational work, continuously improve platform uptime, operational efficiency, and customer experience, and help build one of the industry’s first AI-native Infrastructure & Reliability organizations, with no limits on AI tooling or compute.
Key Responsibilities
Production Reliability
- Own production reliability, responding to and resolving customer-impacting incidents
- Execute production deployments and infrastructure changes with strong operational discipline
AI Agent Development
- Build and improve AI agents for incident triage, change validation, and RCA generation
- Develop auto-remediation capabilities for production issues
Automation & Engineering
- Write production code, automation, runbooks, and AI workflows that eliminate repetitive operational work
Continuous Improvement
- Continuously improve platform uptime, operational efficiency, and customer experience
Qualifications & Requirements
Experience Requirements
- 5+ years operating enterprise SaaS platforms in Infrastructure, Platform Engineering, DevOps, Cloud Operations, or SRE
- Strong AWS production experience, including large-scale cloud infrastructure and incident response
Essential Skills
- Hands-on engineer who enjoys troubleshooting complex production systems and writing automation
- Experience using AI engineering tools such as Claude Code, Codex, Cursor, Warp, or similar
- Passion for building AI-powered operations, automation, and autonomous infrastructure
- Excellent written and spoken English
About the Opportunity
This role offers the opportunity to help build one of the industry’s first AI-native Infrastructure & Reliability organizations, where autonomous agents investigate incidents, validate hypotheses, generate RCAs, and safely remediate production issues. The culture is AI-first, with no limits on AI tooling or compute, fully remote, and part of a global team operating enterprise-scale SaaS infrastructure.
Career Excellence: Help build the future of autonomous infrastructure and AI-powered incident response, in a fully remote role with an AI-first culture and no limits on tooling or compute.
Who Should Apply?
- Senior SRE/DevOps Engineers: With 5+ years operating enterprise SaaS platforms
- AWS Infrastructure Specialists: Experienced with large-scale cloud infrastructure and incident response
- AI Engineering Tool Users: Comfortable with Claude Code, Codex, Cursor, or Warp
- Automation-Focused Engineers: Passionate about building AI-powered operations and autonomous infrastructure
- Remote-First Technical Professionals: Comfortable working as part of a global, distributed team
Recently Opening Job👇